Experimentation & CRO
CRO and A/B testing: build a useful experiment programme
Build a CRO programme from customer evidence to a trustworthy A/B test. Learn how to choose hypotheses, measure outcomes and make release decisions.
Conversion rate optimisation starts with a useful question about the customer journey. A/B testing helps answer that question when you can expose comparable groups to different experiences and measure the result reliably.
The difficult part is rarely inventing more variations. It is deciding which customer problem deserves attention, what an experiment can establish and whether the observed change justifies release. A busy testing calendar can produce little useful learning if those decisions remain vague.
If you manage an e-commerce or digital product team, build a programme that connects research, hypotheses, delivery and interpretation. This guide explains that connection. It gives you a practical way to organise experiments while protecting customers and avoiding conclusions the data cannot support.
CRO also includes work that should be fixed directly. A broken payment step or an inaccessible required field needs attention because it prevents use. You do not need a conversion experiment to decide whether customers should be able to complete the task.
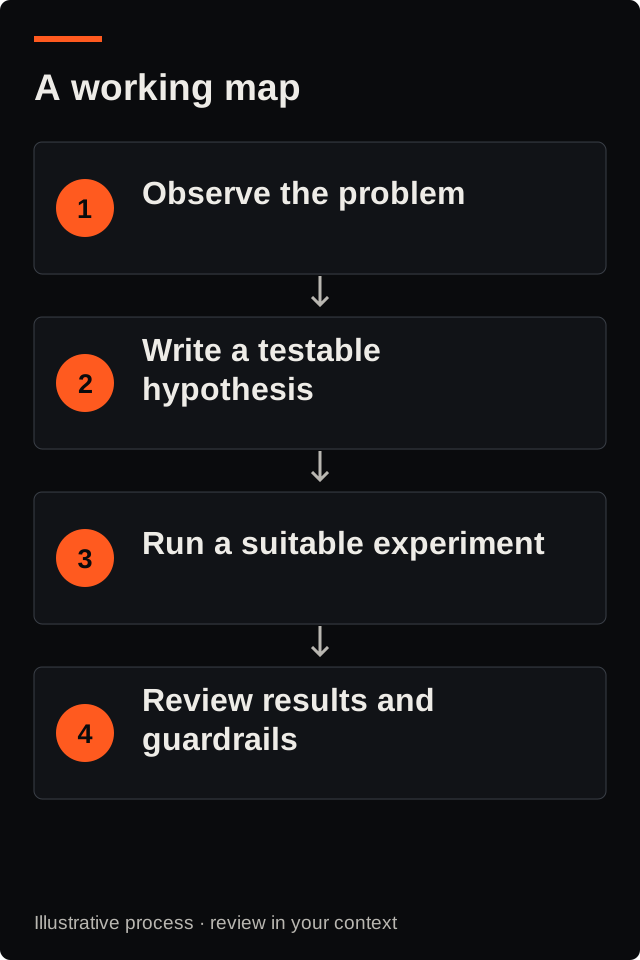
Start with a defined conversion and journey
Specify the action that matters and who has a reasonable opportunity to perform it. A purchase conversion rate can use users, sessions or another defined unit. Different denominators produce different figures, so make the choice visible before comparing results.
Map the journey that leads to the action. For an online shop, visitors may need to find a suitable product, understand delivery, confirm compatibility and complete payment. A single overall rate cannot reveal which part of that journey creates friction.
Use several evidence sources. Funnel data can show where activity stops. Support requests can explain recurring questions. Usability sessions can reveal failures in context. Each source has limitations; combine them to form a plausible question rather than treating one chart as a diagnosis.
Keep business conditions in view. Stock, price, acquisition mix and seasonality can affect conversion independently of a page change. Record relevant changes so a later review can distinguish an experiment result from a broader movement in the business.
Research the problem before proposing the variation
Begin with an observation. “People often ask whether this item fits their existing setup” is more useful than “we should add a badge”. The observation points to an information need. The badge is only one possible way to address it.
Separate frequency from consequence. A problem that occurs rarely can still block important customers. A common hesitation may be harmless if people resolve it easily. Prioritisation needs both the reach of the problem and its impact on the intended task.
Avoid interpreting behavioural data as direct access to motivation. A long pause may indicate confusion, comparison, distraction or careful reading. Pair the signal with contextual research before assigning a psychological explanation.
For that bridge, read how to turn a psychological insight into a test hypothesis. The practical discipline is to treat the explanation as testable, rather than assuming a familiar bias predicts the outcome.
Write a hypothesis that can be wrong
A useful hypothesis names the audience, observed problem, proposed change, expected mechanism and outcome measure. It also identifies what evidence would challenge the idea. The aim is a statement that supports an experiment, not a promise that the variation must win.
For example, you may hypothesise that showing reliable compatibility information near a product decision will reduce uncertainty for eligible visitors. You can then define a relevant outcome and guardrails. The specific page and information still require design and verification.
Microsoft's pre-experiment guidance recommends clear hypotheses and success metrics. Use that principle to keep the expected effect and the means of measuring it connected.
Avoid bundling unrelated changes unless the decision concerns the bundle. If you alter messaging, pricing presentation and navigation together, the experiment may estimate the effect of that combined experience. It cannot tell you which component caused the result. The dedicated hypothesis guide develops this step.
Prioritise by evidence and learning value
Use a consistent brief for candidates. Record the problem, supporting evidence, affected audience, expected value, implementation effort and measurement feasibility. The brief makes discussion more useful than a score with no explanation.
Treat scoring systems as aids to judgement. Multiplying subjective ratings can create precise-looking rankings from weak evidence. A lower-ranked idea may still deserve attention if it resolves a dependency or answers a strategic question.
Check feasibility before scheduling. Can the traffic support a decision within a useful period? Can the outcome be measured consistently? Can you deliver the variation without changing the assignment or losing events? If not, more customer research or a direct improvement may be appropriate.
Keep a separate list for important fixes. An experiment backlog should not become a queue where accessibility problems or broken functions wait behind speculative growth ideas. Distinguish a requirement to provide a usable service from an uncertain optimisation opportunity.
Design the experiment around the decision
Choose the randomisation unit and eligible population. Returning users should receive a consistent experience when the design requires it. If accounts contain several collaborating users, account-level assignment may be more appropriate than treating every visit as independent.
Define a primary outcome and a small set of guardrails. Purchase rate may improve while margin falls or support contacts increase. Guardrails protect against an attractive result that harms another part of the business or customer experience.
Plan the analysis with the statistical method actually configured. Optimizely's methods overview distinguishes fixed-horizon, Bayesian and sequential approaches. Their outputs and stopping rules should not be treated as interchangeable.
Estimate whether you can detect an effect worth acting on. Even where the engine supports sequential monitoring, traffic and outcome frequency still constrain useful learning. A test with insufficient information does not become decisive because the dashboard updates continuously.
Check implementation and data quality
Validate assignment, exposure and event collection before relying on the results. Confirm that the experience appears for the intended audience and that the key outcome is recorded consistently in both groups.
Inspect sample ratio mismatch when the observed allocation differs materially from the planned allocation. That signal calls for investigation. It can indicate an assignment or collection problem that compromises the comparison; it is not evidence that one variation persuaded more people.
Check common conditions, including mobile devices, consent states and relevant browsers. Examine whether the variation adds delay, hides required information or changes the accessibility of the journey. A visual review alone will not catch every failure.
Keep the release identifiable. Record the version, start time, scope and material changes during the test. If a separate campaign or product release changes the journey, capture it in the experiment record and assess whether it affects interpretation.
Hypothetical example: delivery information on a product page
Imagine a shop where research suggests some visitors struggle to find delivery conditions. This is a hypothetical example, not a description of a Whirlpool experiment. The team proposes presenting accurate delivery information closer to the purchase decision.
The primary outcome is purchase among a defined eligible population. Guardrails include margin-related outcomes, support questions and page performance where measurable. The team checks that the information is accurate for every included product and destination.
An increase in clicks on the delivery panel would show engagement with that panel. It would not establish a purchase benefit. An increase in purchases with worse support outcomes would require judgement about the trade-off.
If the result is inconclusive, the team records the estimate and uncertainty. It can investigate whether visitors noticed the information or whether the original problem was misdiagnosed. It does not turn “no clear decision” into a win because a secondary measure looked positive.
A compact experiment brief
Complete this before development so design, analytics and business stakeholders can challenge the same proposal.
Swipe or use the arrow keys to see every column.
| Field | What to record |
|---|---|
| Observation | What happened, with evidence and limitations |
| Audience | Who has the problem and can enter the test |
| Hypothesis | Why the proposed change should affect behaviour |
| Variation | What changes and what stays comparable |
| Outcome | Primary measure, denominator and attribution window |
| Guardrails | Harm or trade-offs the team must detect |
| Analysis | Method, decision rules and data-quality checks |
| Decision | Release, revise or stop conditions and owner |
The brief should also include how customers can recover from a failure. A variation that touches a critical step may need a quick suspension route. Assign that responsibility before the test starts.
Keep the document short enough to use. Detailed designs and analysis notes can sit alongside it. The brief's job is to make the argument reviewable and preserve the intended decision.
Interpret results without manufacturing a winner
Read the effect estimate and uncertainty alongside data quality and guardrails. Statistical significance is evidence within a model and design, not a guarantee of a profitable release.
Distinguish relative change from percentage points. A hypothetical change from 2% to 2.2% is a 10% relative increase and a 0.2 percentage-point increase. State which one you report. Avoid multiplying separate test lifts as if they automatically predict an overall programme result.
My profile includes an owner-reported +57% conversion result for Whirlpool EMEA. The available profile material does not include experiment-level data, baselines or test variants. The article on e-commerce conversion improvements explains how to discuss that result without inventing a case history.
For the statistical questions, read significance and peeking. The right interpretation depends on both the method and the way the experiment was run.
Choose the next investigation deliberately
Use qualitative research for CRO when the customer problem is not yet understood. The experiment backlog guide helps compare candidates by evidence and decision relevance.
Before launch, define guardrail metrics for possible harm and inspect whether low traffic makes the proposed decision feasible. If the intervention adapts an experience to a targeted group, the personalisation experiment guide separates targeting from the treatment effect.
These questions support different decisions. Choose the one that addresses the current uncertainty rather than adding another variation to the calendar.
Make learning part of the next decision
Record what the experiment established, what it did not establish and how the result changes the next hypothesis. A well-run negative test can prevent a costly release. An inconclusive test can reveal a measurement or traffic constraint worth addressing.
Review the programme by decision quality, not only test count or win rate. Those targets can encourage weak experiments and selective reporting. Look for better problem diagnosis, clearer hypotheses and releases supported by evidence.
Start with one journey, one problem and a brief the team can challenge. Build the cadence around decisions that matter to customers and the business.
Discuss your CRO programme if you have ideas and traffic but need a more reliable route from research to release.
Apply this to your project
Tell me the decision you are facing, the constraints and what you have already tried.
Keep exploring
How to write an A/B test hypothesis worth testing
Write an A/B test hypothesis from evidence, audience and expected behaviour. Use a practical worksheet to choose metrics and interpret a negative result.
A/B test guardrail metrics: protect the whole journey
Choose A/B test guardrail metrics that protect quality, performance and downstream outcomes. Define thresholds and decisions before launching a test.
Experiment backlog prioritisation: choose better tests
Prioritise your experiment backlog using evidence, traffic and decision value. Build a practical queue that turns observations into useful A/B tests.